Configure Oracle E-Business Suite as a data pipeline source
Set up Oracle E-Business Suite (EBS) as a data pipeline source to extract and sync records from EBS database tables to your destination. The pipeline connects directly to the EBS database through an on-prem agent.
Use this guide to set up a database user, connect to EBS, configure your pipeline, and review sync behavior, data type handling, and limitations.
Features supported
The following features are supported when you use Oracle E-Business Suite as a pipeline source:
- On-prem connectivity: Connect to the EBS database through an on-prem group. Cloud connections aren't supported.
- Full sync and incremental sync: Sync all rows on each run, or sync only new and updated rows based on a change tracking column. Refer to Sync modes for more information.
- Table-level object selection: Select individual tables from any schema the database user can access.
- Primary key detection: Detect primary keys from database constraints and EBS table metadata. Refer to Primary keys for more information.
- Delete tracking: Mark records deleted at the source as deleted in the destination when a table runs in full sync mode.
- Schema drift detection and handling: Detect and apply schema changes automatically with Auto-sync new fields, or keep the schema fixed with Block new fields.
- Field-level data protection: Hash or replicate sensitive fields as is before the data reaches your destination.
- Configurable sync frequency: Schedule syncs on a time-based interval or with a cron expression. The minimum supported interval is 15 minutes.
Prerequisites
Connecting Oracle E-Business Suite as a data pipeline source requires:
- An Oracle EBS database reachable from your on-prem agent host
- An on-prem agent running version 31.0 or later. Refer to the on-prem agent documentation for setup steps.
- A database user with
SELECTaccess to the EBS tables you plan to sync. Refer to Set up a database user for the required grants. - The database host, port, service name, username, and password for your EBS database
Set up a database user
The database user for the pipeline must have SELECT on each table you plan to sync. Your database administrator can use an existing user or create a new user. Replace WORKATO in the following examples with the user's name:
Create the user and grant login access:
CREATE USER WORKATO IDENTIFIED BY <password>;
GRANT CONNECT TO WORKATO;
Grant SELECT on each table you plan to add as an object in your pipeline:
GRANT SELECT ON <schema>.<table_name> TO WORKATO;The pipeline fails with the error Table '<SCHEMA>.<TABLE_NAME>' is not available. It may have been deleted, or your credentials lack permission to access it if the user doesn't have SELECT on a table you add.
Grant SELECT on the following EBS metadata tables in the APPLSYS schema:
GRANT SELECT ON APPLSYS.FND_TABLES TO WORKATO;
GRANT SELECT ON APPLSYS.FND_PRIMARY_KEYS TO WORKATO;
GRANT SELECT ON APPLSYS.FND_PRIMARY_KEY_COLUMNS TO WORKATO;
GRANT SELECT ON APPLSYS.FND_COLUMNS TO WORKATO;
Workato reads these tables to detect the primary key for tables that don't have a primary key, unique constraint, or unique index in the database. Tables without a database key fail to load with an Error running query on agent error if the user can't read these tables. Refer to Primary keys for more information.
Supported connection types
Oracle E-Business Suite pipelines support username and password authentication through an on-prem group.
Data pipelines use the Oracle E-Business Suite (Data Pipelines) connector, which reads directly from the EBS database. Connections you create with the Oracle E-Business Suite connector for recipes use Integrated SOA Gateway REST services and aren't available as a pipeline source. You must create a separate connection for your pipeline.
CLOUD CONNECTIONS NOT SUPPORTED
You must select an on-prem group in the Connection type field. The connection form doesn't show the database fields when you select Cloud.
Connect to Oracle E-Business Suite
Complete the following steps to connect Oracle E-Business Suite as a data pipeline source:
Select Create > Connection or press C twice.
Search for Oracle E-Business Suite (Data Pipelines) and select it as your app.
Enter a name in the Connection name field.
Use the Location drop-down menu to select the project where you plan to store the connection.
Use the Connection type drop-down menu to select the on-prem group that can reach your EBS database.
Enter the service name of your EBS database in the Service name field.
Enter the host address of your EBS database in the Database host field.
Enter the port number in the Database port field. The default Oracle port is 1521.
Enter the username of the database user from Set up a database user in the User name field.
Enter the password in the Password field.
Optional. Enter a schema in the Schema field.
Select Connect to verify and save the connection.
Configure the pipeline
Complete the following steps to configure Oracle E-Business Suite as your data pipeline source:
Select Create > Data pipeline or press C+I.
Enter a name for the data pipeline in the Data pipeline name field.
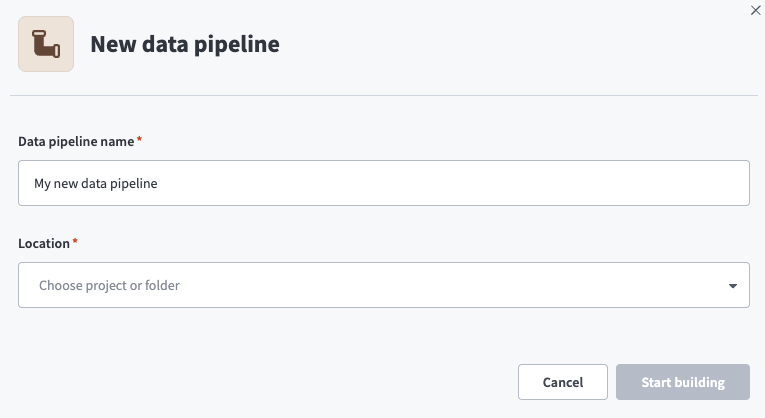 Data pipeline setup
Use the Location drop-down menu to select the project where you plan to store the data pipeline.
Click Start building.
Click the Extract new/updated records from source app trigger. This trigger defines how the pipeline retrieves data from Oracle E-Business Suite.
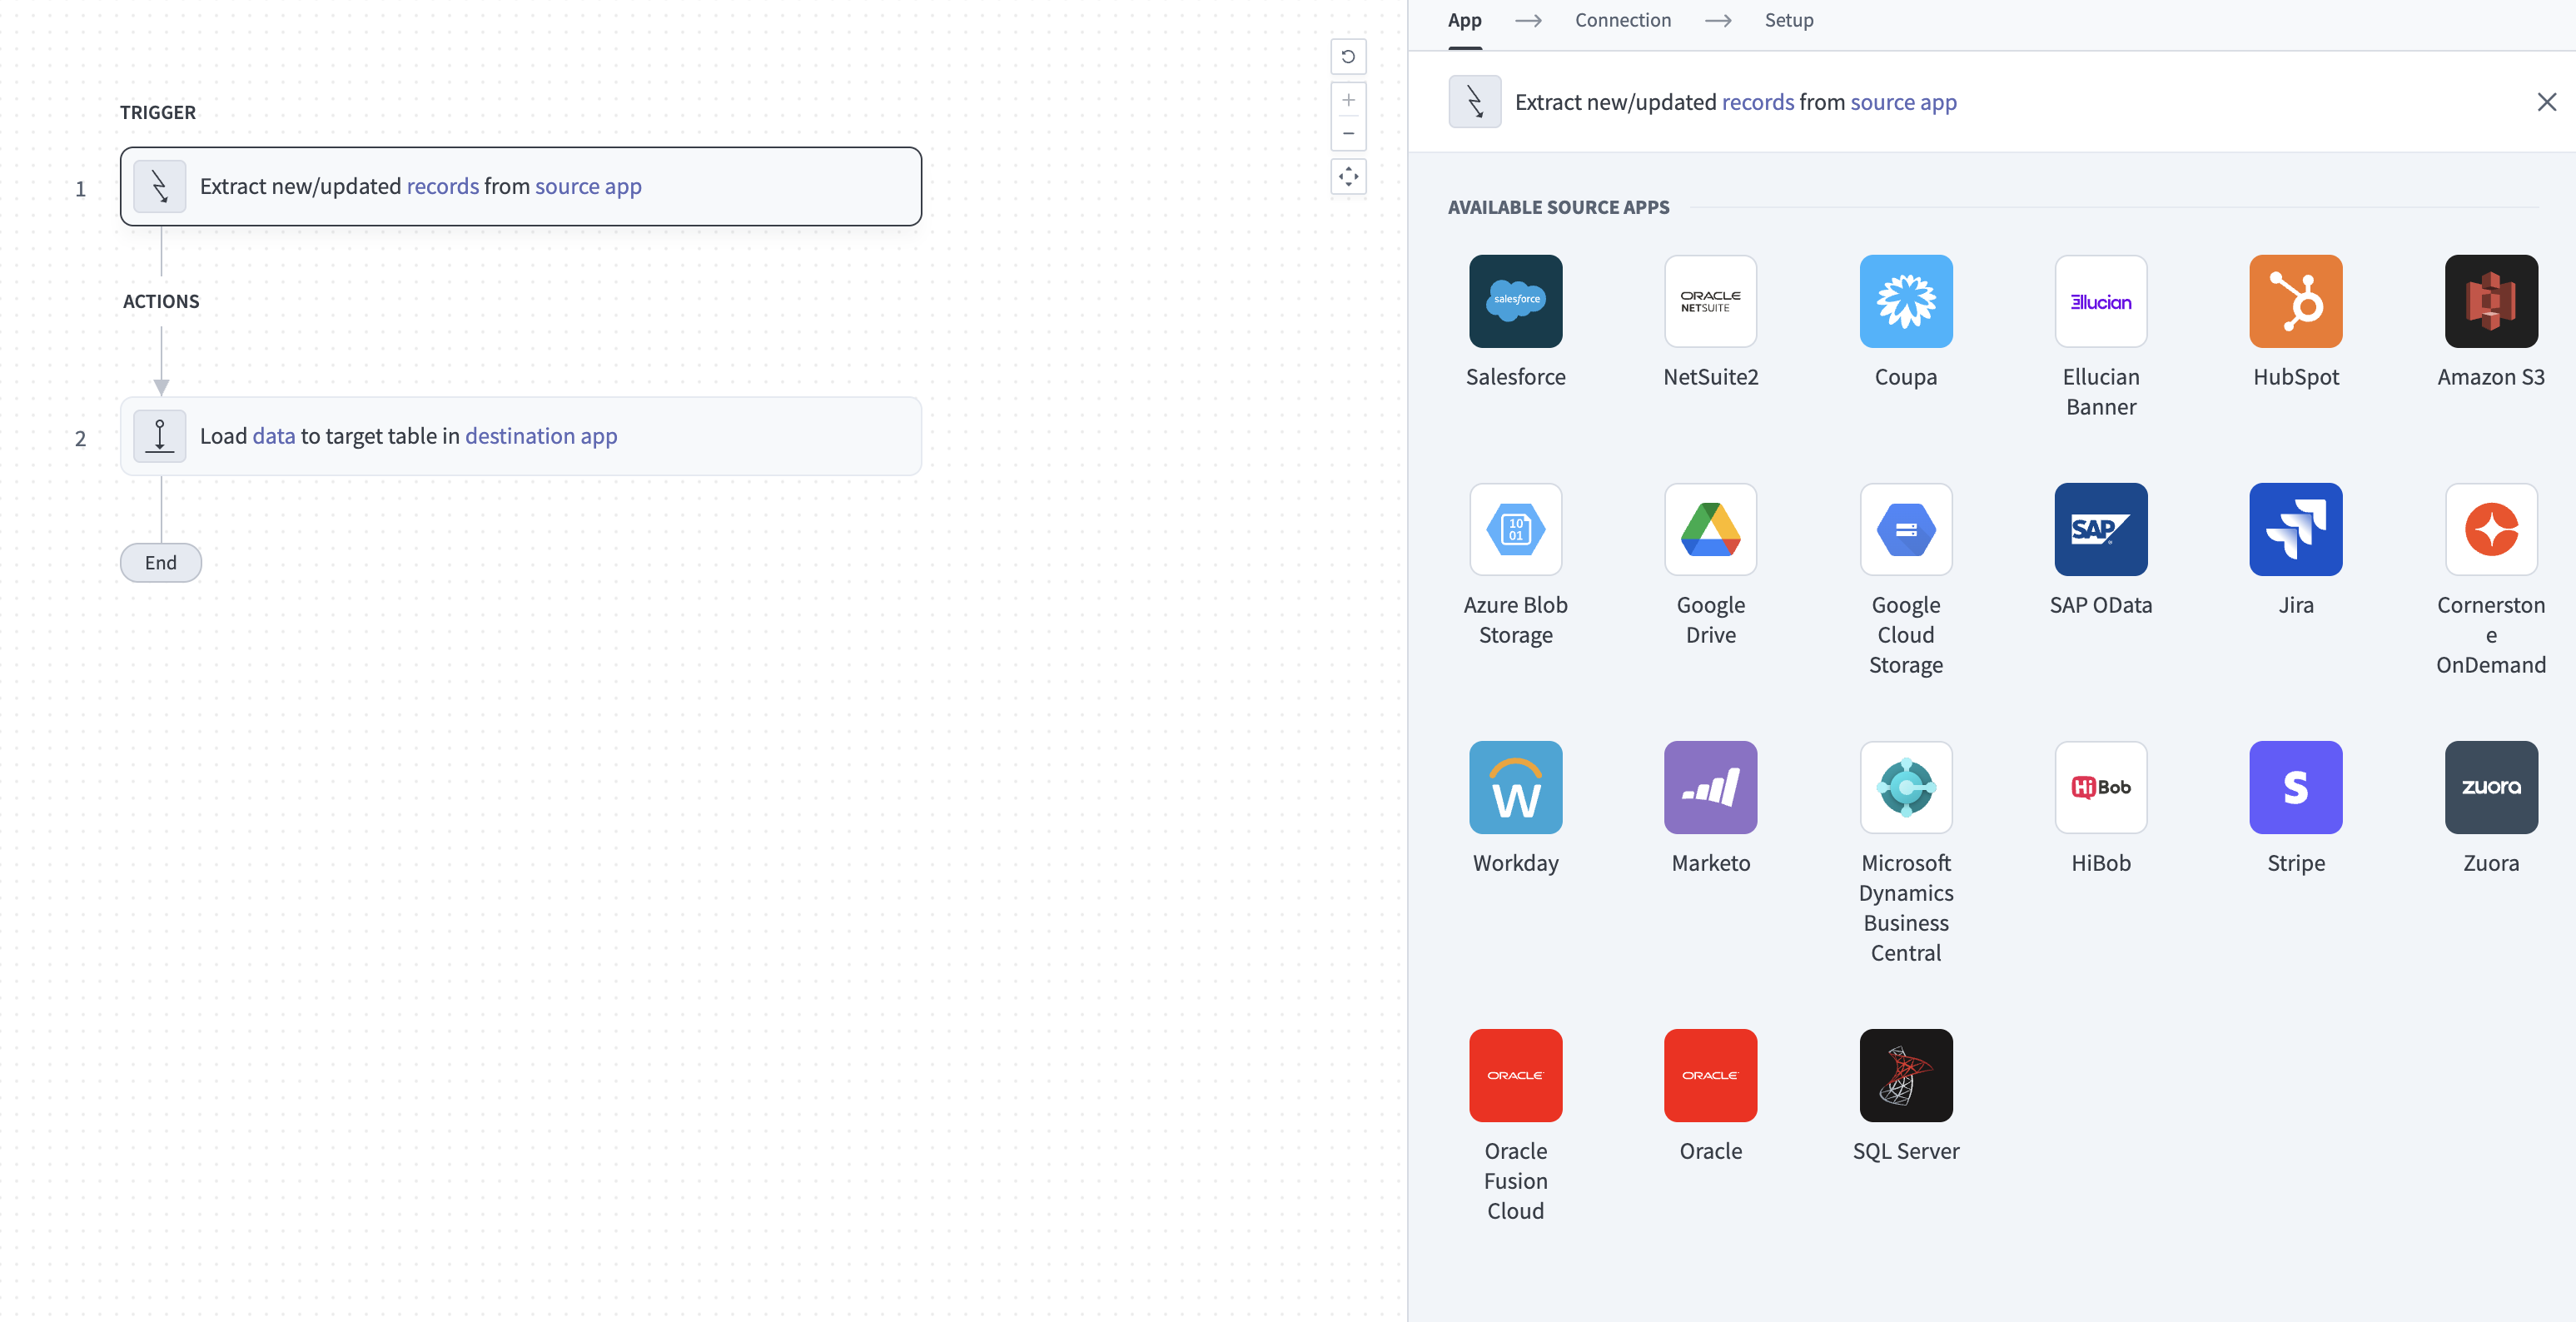 Configure the Extract new/updated records from source app trigger
Use the Your Connected Source Apps drop-down menu to select Oracle E-Business Suite (Data Pipelines).
Choose the Oracle E-Business Suite connection you plan to use for this pipeline. Alternatively, click + New connection to create a new connection.
Click Add object to open the Add new objects panel.
Search or browse the list of available EBS tables, select the tables you plan to sync, and click Add.
Review and customize the schema for each selected object. The pipeline automatically fetches an object's schema when you select it. This ensures the destination matches the source.
Expand an object to view associated fields. Keep all fields selected to extract all available data, or deselect specific fields to exclude them from data extraction and schema replication.
Optional. Click the gear icon next to a table to open Sync mode settings and use the Sync mode drop-down menu to select Full sync or Incremental, then click Save.
The sync mode defaults to Incremental for every table. Incremental sync fails for tables that don't have one of the default change tracking columns. Select a column in the Change tracking column field for these tables, or select Full sync.
Changing the Sync mode or Change tracking column triggers a full re-sync of the table on the next pipeline run.
Optional. Configure field-level data protection by expanding an object and choosing how to handle each field:
- Replicate as is: Data values at the source replicate identically to the destination.
- Hash: Hash sensitive data values in the field before syncing to your destination.
Workato recommends hashing personally identifiable information (PII) and other sensitive fields.
Click Add object again to add more objects. Repeat this step to include additional Oracle E-Business Suite objects in your pipeline.
Use the Choose how to handle schema changes drop-down menu to select a schema drift handling option:
- Auto-sync new fields: Automatically detects and syncs new fields added in the source.
- Block new fields: Keeps the schema fixed after the pipeline starts. You must add new fields manually. This option may cause the destination to fall out of sync if the source schema updates.
Refer to Schema replication and schema drift management for more information.
Choose either a standard time-based schedule or define a custom cron expression in the Frequency field. This determines how often the pipeline syncs data from Oracle E-Business Suite to the destination.
The start date applies only to tables with a change tracking column. Refer to Full sync for more information.
Supported objects
Oracle E-Business Suite data pipelines sync data from tables in the connected EBS database. Workato lists every table the database user can access, across all schemas, when you click Add object. Each table appears as <SCHEMA>.<TABLE_NAME> and syncs as a separate table in your destination.
Only tables are listed. Views and synonyms aren't available as objects.
Primary keys
Workato identifies the primary key for each table in the following order:
- Database constraints: The table's enabled primary key or unique constraint, or a unique index.
- EBS metadata: The primary key registered for the table in the EBS
FND_PRIMARY_KEYSmetadata table. Workato can read this metadata only if the database user has access to theAPPLSYStables listed in Set up a database user. - ROWID: Workato adds a
ROWIDcolumn as the primary key when neither source explicitly defines a primary key. Refer to Tables keyed by ROWID for how this affects syncs.
Sync modes
Oracle E-Business Suite data pipelines support full sync and incremental sync. The sync mode is configured per table when you add it to your pipeline.
Full sync
A full sync reads the source table on each pipeline run. Use full sync for tables without a change tracking column. Full syncs of large EBS tables can take longer and use more resources than incremental syncs.
The rows a full sync reads depend on the pipeline start date in the When first started, this pipeline should pick up records from field:
- Tables with a change tracking column: Full syncs read only rows with a change tracking value on or after the start date. Rows with an earlier or null change tracking value don't sync, and aren't marked as deleted by delete tracking. Full syncs read every row if you leave the start date blank.
- Tables without a change tracking column: Full syncs read every row, regardless of the start date.
Incremental sync
An incremental sync reads only rows whose change tracking column changed since the previous run. The first run of an incremental table is a full sync. Workato checks for the following columns in this order and selects the first one that exists in the table as the default change tracking column:
LAST_UPDATE_DATEUPDATEDLAST_MODIFIED_DATE
You can select a different column in the Change tracking column field of the table's sync settings. Incremental syncs fail for tables that don't have one of the default columns and have no column selected. Select a change tracking column for these tables or switch them to full sync. Refer to Configure the pipeline for the sync settings step.
Incremental sync detects a changed row only when the change tracking column changes. Incremental syncs don't pick up rows updated without a new change tracking value, or rows with a null change tracking value.
Delete tracking
Delete tracking depends on the sync mode:
- Full sync: Workato marks records deleted at the source as deleted in the destination on the next full sync.
- Incremental sync: Deletes aren't detected, because each run reads only rows with a new change tracking value.
Schema and data type handling
Workato maps Oracle column types to destination types as follows:
| Oracle type | Synced as |
|---|---|
NUMBER, INTEGER, INT, SMALLINT, DECIMAL, NUMERIC | Decimal |
FLOAT, BINARY_FLOAT, BINARY_DOUBLE | Double |
BOOLEAN | Boolean |
DATE, TIMESTAMP | Timestamp without time zone |
TIMESTAMP WITH TIME ZONE, TIMESTAMP WITH LOCAL TIME ZONE | Timestamp with time zone |
CHAR, NCHAR, VARCHAR2, NVARCHAR2, LONG, ROWID | String |
CLOB, NCLOB, XMLTYPE, RAW, LONG RAW, BLOB | String, using the destination's maximum string length |
INTERVAL types, SDO_GEOMETRY, and other types | String |
Numeric columns sync as strings instead of decimals when the column doesn't have declared precision, a negative scale, a precision greater than 38, or a scale greater than the declared precision. Oracle DATE columns include a time of day that sync as timestamps.
Limitations
The following limitations apply when you use Oracle E-Business Suite as a data pipeline source:
Tables keyed by ROWID
Workato uses ROWID as the primary key for tables that don't have a primary key in the database or in EBS metadata. These tables show a ROWID field in the schema when you add them to your pipeline. A ROWID reflects where Oracle physically stores the row, so it can change when the row moves on disk, even if the row's contents don't change. Refer to the Oracle ROWID pseudocolumn documentation for more information.
A full sync can miss a row if the row's ROWID changes during the sync. The next run picks up the row if the table uses full sync, because each full sync reads the table again. Incremental syncs don't pick up the missed row unless the change tracking column changes. Run an object re-sync of the table to load the latest data into your destination.
USE FULL SYNC FOR ROWID TABLES
Use full sync for tables keyed by ROWID if you're unsure whether the table rows move on disk.
Minimum sync frequency
The minimum supported sync interval is 15 minutes.
Last updated: